~/divyam/stories what-if-counterfactual-history-engine
ai junction · ai systems
WHAT IF? An Engine That Keeps an AI's Facts and Guesses Apart
A multi-agent RAG pipeline that answers historical 'what if' questions with grounded, cited, confidence-scored reasoning. Verified facts and simulated consequences are always kept separate.
- when
- May 2026
- role
- AI/ML Engineer
- stack
- PythonLangGraphChromaDBPydanticCerebrasStreamlitsentence-transformers
Overview
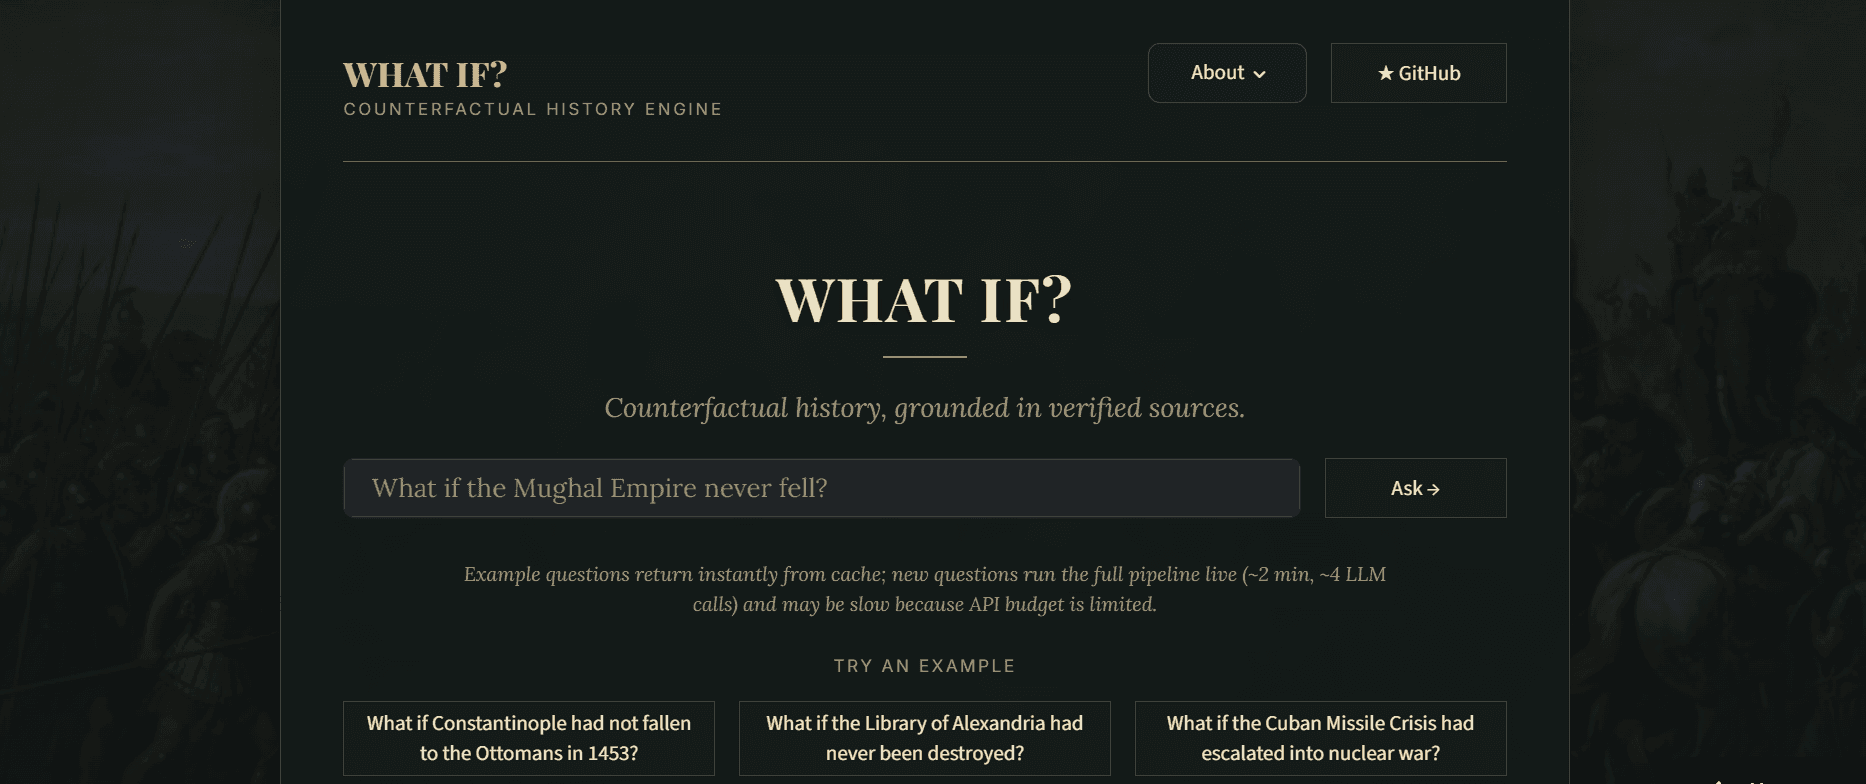
WHAT IF? is a counterfactual history engine built around one idea: honesty about uncertainty is the product.
Ask it any 'what if' question about history. Instead of one confident, unverifiable answer, it returns two clearly separated outputs. A 'What We Know' section built from retrieved, cited historical evidence. And a 'What Might Have Happened' section where every speculative step is explicitly labeled as such.
Under the hood it runs a 5-agent LangGraph pipeline. It retrieves context, grounds each claim to its source chunk, constructs a bounded causal chain, and scores each step's confidence purely by how much verified evidence backs it. Not by asking the model how certain it feels.
Problem
Large language models are very good at sounding certain. That is exactly the problem.
Ask an LLM a counterfactual history question and it blends verified facts, reasonable inference, and confident hallucination into one fluent paragraph. No sources. No labels. No signal about which parts to trust.
The answer reads like authoritative analysis but there is no way to audit it.
This failure mode is not unique to history. Any domain where confusing fact with speculation carries real cost — medicine, law, finance — faces the same issue. A raw LLM gives you an answer. It does not give you a reason to trust or distrust any part of it.
Solution
The pipeline splits the problem into four distinct stages: retrieve, ground, reason, and score. Each stage is handled by a dedicated agent that returns a validated Pydantic model, never a raw string.
The grounding layer extracts only claims that can be tied to a specific retrieved chunk and classifies each one as VERIFIED, DEBATED, or BACKGROUND.
The reasoning agent builds a causal chain on top of that grounded context. Every simulated step must carry a [SIMULATED] label and an [EVIDENCE: chunk_id] tag pointing to the exact chunk it draws from.
Confidence is computed, not asked. Agent 5 counts how many verified facts back each reasoning step and assigns HIGH, MEDIUM, LOW, or SPECULATIVE. The model's self-reported confidence is captured for contrast but never used as the actual score.
A hard cap of 4 causal steps acts as a hallucination guard. The longer the chain, the more speculative it becomes, so the system refuses to go further.
Architecture
The system has two planes. An offline ingestion pipeline that builds the vector store once, and an online query pipeline that runs per question.
Ingestion downloads 18 Wikipedia articles, chunks them into roughly 300-token segments with 100-token overlap, embeds them using the local all-mpnet-base-v2 model with no API call, and upserts them into a persistent ChromaDB collection. 1,466 chunks total.
The online pipeline is a LangGraph StateGraph with 5 nodes wired by conditional edges. Every node failure is caught and recorded gracefully. The graph halts at END rather than crashing.
A key design detail: ChromaDB always returns top-k results regardless of relevance. An out-of-corpus question returns a full pool of low-similarity junk rather than an empty result. So the fallback is triggered by a cosine similarity floor of 0.6, not by an empty check.
When no hit clears that floor, a dynamic Wikipedia fallback fires. It fetches live pages, chunks and embeds them locally, upserts into ChromaDB, and re-runs the same vector search. This entire fallback makes zero LLM calls.
Highlights
The most significant engineering decisions were around reliability and honesty rather than raw capability.
- 5-agent LangGraph StateGraph with graceful error handling at every node. The pipeline never crashes, it halts honestly.
- RAG pipeline with ChromaDB and local all-mpnet-base-v2 embeddings. Zero API cost for retrieval.
- Dynamic Wikipedia fallback triggered by cosine similarity floor below 0.6. Fetches, chunks, embeds, and re-searches live with zero LLM calls.
- Grounding layer validates every cited chunk_id against the actual retrieved pool. Fabricated IDs are dropped, not trusted.
- Per-agent LLM temperatures tuned to task: T=0.1 for query parsing, T=0.0 for grounding, T=0.3 for reasoning.
- Confidence scored by evidence count using pure logic with no LLM. HIGH (2 or more verified facts), MEDIUM (1 verified or analogy), LOW (only debated or background), SPECULATIVE (ungrounded).
- Hard 4-step causal cap as a hallucination guard. Extra steps are dropped with a warning.
- Pydantic v2 validation at every agent boundary with one corrective retry on JSON-mode failures.
- SHA-256-keyed result cache with pre-warmed example answers. Known questions return instantly at zero cost. Errors are never frozen in.
- Automated evaluation suite with 4 rule-checks across 8 test cases. The step cap held 8 out of 8.
Evaluation
The evaluation suite runs the full 5-agent chain over 8 curated counterfactual questions and applies four automated checks per case.
C1 verifies every reasoning step carries a [SIMULATED] label. C2 verifies every step cites a chunk_id that exists in the grounded context. C3 verifies no more than 4 causal steps are produced. C4 verifies no simulated content is presented as fact.
C3 held across all 8 cases. C1 and C4 passed 7 out of 8. C2 is the weakest at 4 out of 8. The reasoning model sometimes emits fabricated chunk_ids. These are flagged and downgraded to SPECULATIVE rather than silently accepted.
The honest acknowledgment of C2 is intentional. The system is designed to surface its own failure modes rather than hide them.
Repository
pipeline_config = {
  "agents": [
    {"id": 1, "name": "understand_query",  "llm_calls": 1, "temperature": 0.1},
    {"id": 2, "name": "retrieve_context",  "llm_calls": 0, "fallback": "wikipedia_dynamic"},
    {"id": 3, "name": "ground_context",    "llm_calls": 2, "temperature": 0.0},
    {"id": 4, "name": "reason",            "llm_calls": 1, "temperature": 0.3},
    {"id": 5, "name": "score_reasoning",   "llm_calls": 0, "method": "evidence_count"},
  ],
  "hallucination_guard": {"max_causal_steps": 4},
  "confidence_levels": ["HIGH", "MEDIUM", "LOW", "SPECULATIVE"],
  "total_api_cost": "0",
}
Outcome
The interesting engineering in this project lived in the guardrails, not the generation.
Structuring uncertainty, deciding what counts as evidence, enforcing that simulations are labeled, and computing confidence rather than asking for it required more careful design than the reasoning pipeline itself.
The final system runs entirely on free-tier APIs and local models at zero cost. It handles out-of-corpus questions through a live Wikipedia fallback with no extra LLM calls, and produces outputs where a reader can audit exactly which claims are verified, which are debated, and which are the model's own inferences.